Case study 04 · Side project
fixmybanana
Upload a handstand photo and a vision model tells you whether you have good form or a banana back, the arched spine every beginner has. I built it as a joke, then used it to show how I test an AI feature before I trust it.
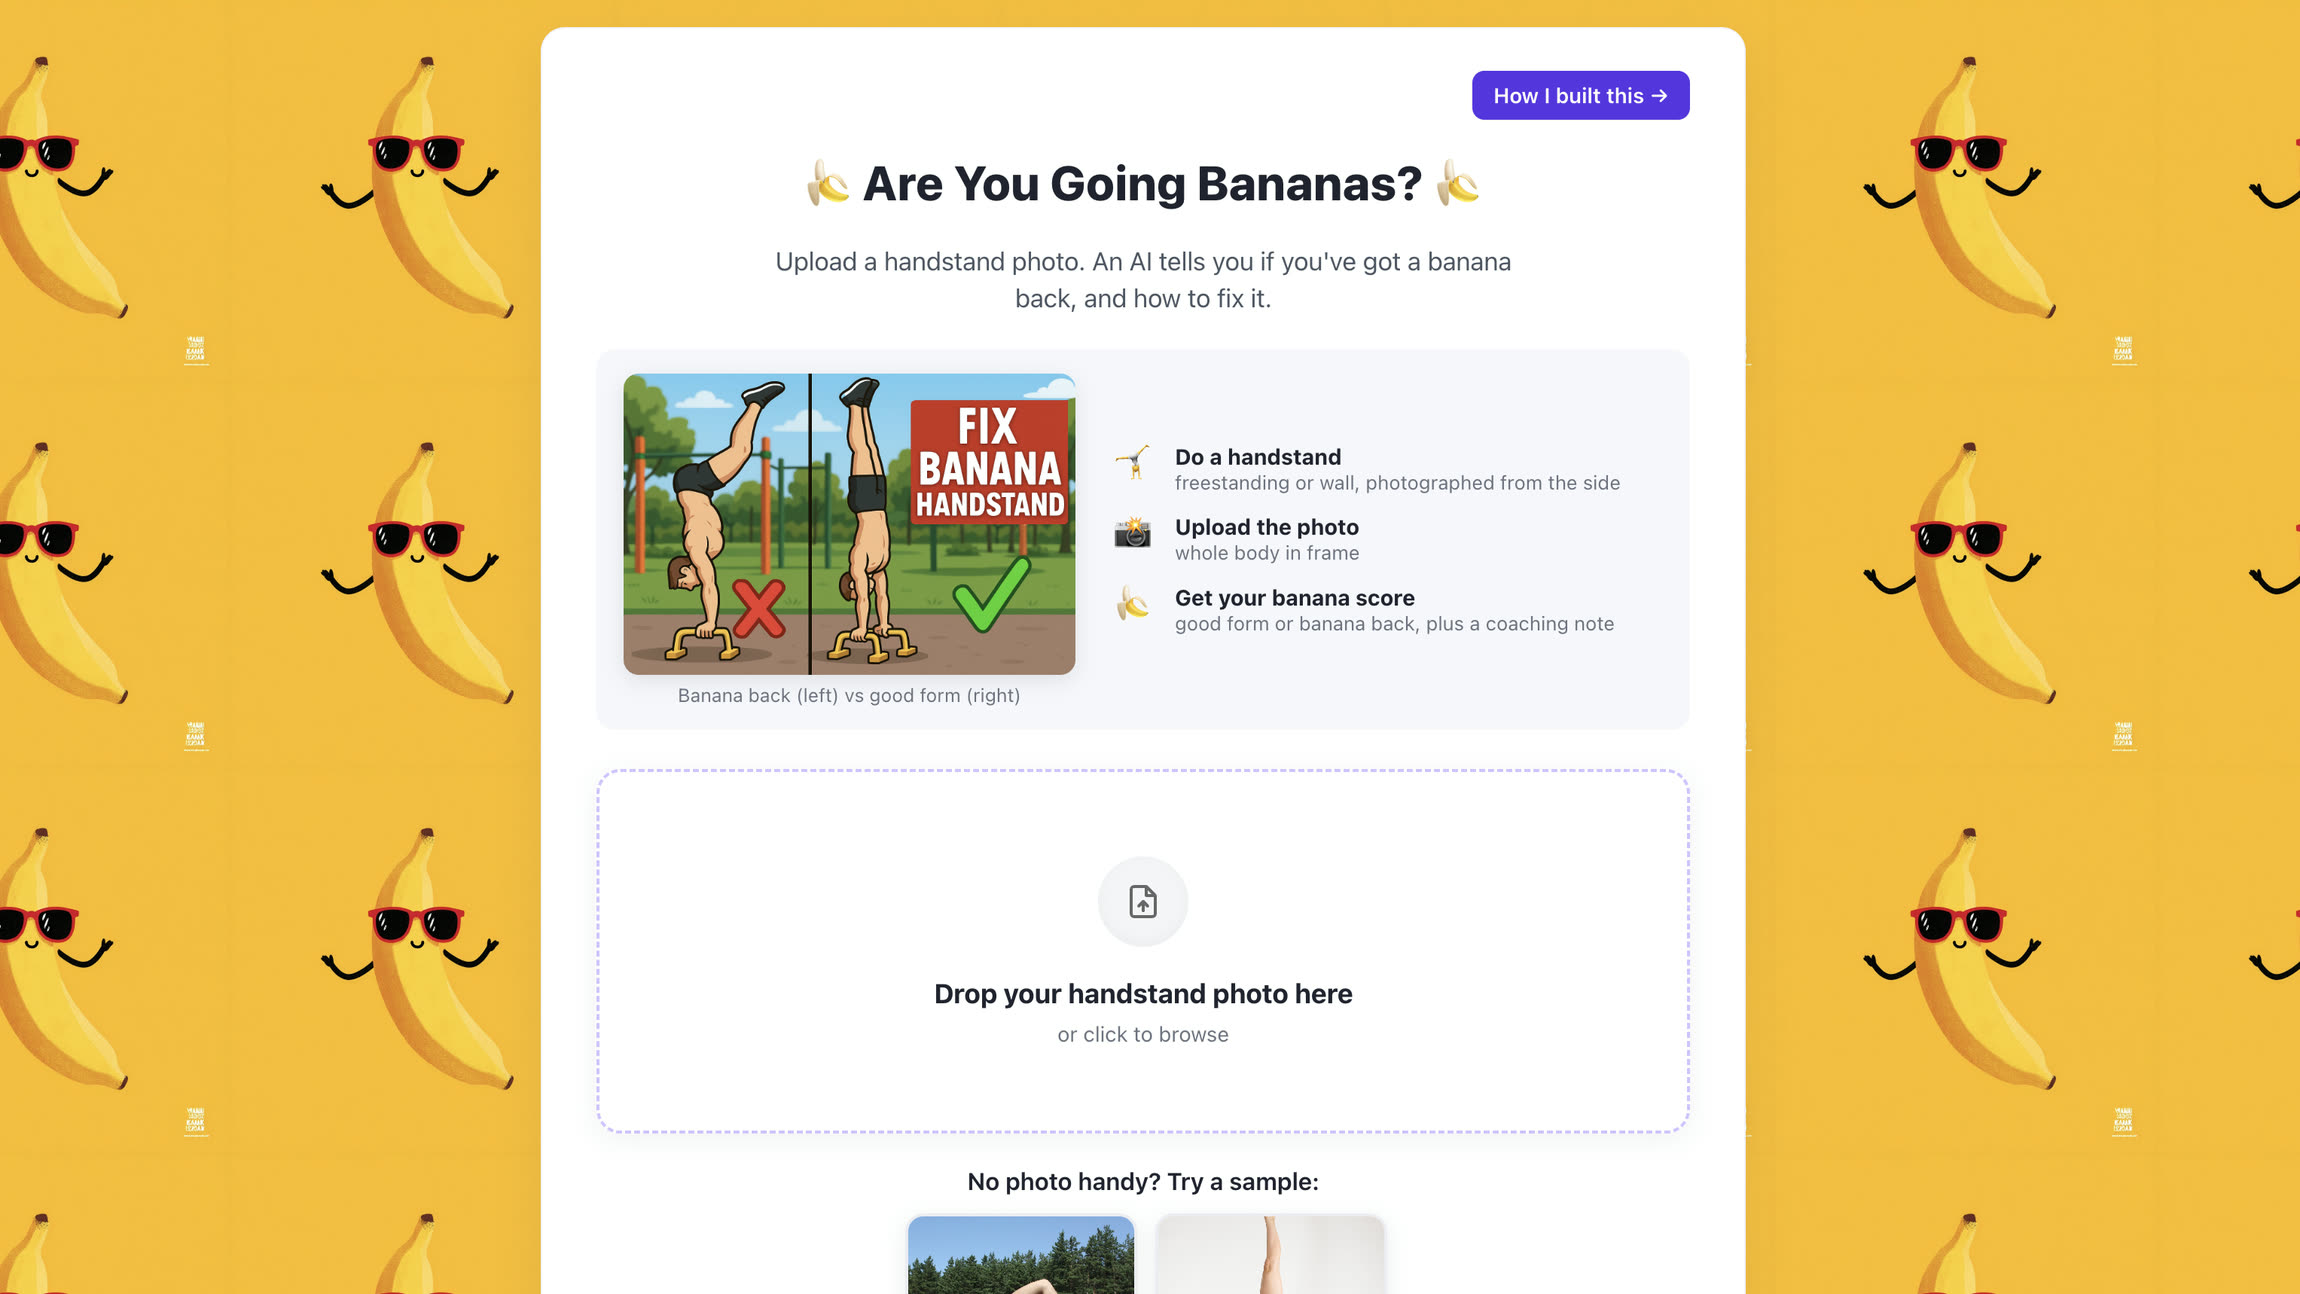
Background
It worked, people laughed, and it proved almost nothing: from the outside it read as photo in, API call, answer out.
As a former personal trainer I can judge a handstand myself, which makes this a rare side project where I am the domain expert. So the real question became: does the model agree with me, how often, and where does it fail?
Solution
Instead of rewriting it, I froze the original as v0 and measured it on a fixed test set. Every later version runs against the same photos, so changes show up as numbers, not impressions.
- The test set covers the edges, not the average upload: side, front and back views, freestanding and wall, dark and low-resolution photos, plus 7 non-handstand controls.
- I labelled every handstand on a 0 to 10 scale (0 is a ruler, 10 is a croissant), then a second labeller (Claude) scored the same set independently with the same rule.
- Every photo ran 5 times, because the same photo doesn't always get the same answer.
Receipts
What failed, in order of size:
- 42 of 235 runs returned neither label. The model refused, and the app showed the refusal as broken text.
- Front and back views: only 4 of 12 came out right.
- Controls: six of seven were refused, the right instinct shown as a broken message. A bronze statue of a handstand was called banana back five times out of five.
- Temperature 0 still wobbled on 17% of photos.
60% on 47 photos has a 95% interval of roughly 45 to 72%. I publish it anyway: a number with its uncertainty is more useful than a clean score.
Not done yet
What v1 and later versions change, each measured on the same 54 photos:
- Give the model a way out: structured output with a "photo not usable" option, so refusals stop looking like bugs.
- Replace the yes or no verdict with a 0 to 10 score.
- Teach the prompt about the failure cases found above.
- Add a third run only when the first two disagree. About a cent more, on borderline photos only.
- A pose-estimation baseline on the same set, to check whether this needs a language model at all.
- Monitoring on real traffic, behind a hard daily spending cap.
Next project